Search engine optimization has crossed a critical threshold. The era of manually conducting site audits using desktop crawlers, copying keyword data into spreadsheets, hand-crafting individual meta tags, and manually checking indexation status is no longer scalable for modern digital organizations. Modern organic search operations require speed, technical consistency, and real-time execution. Deploying robust seo automation tools and enterprise-grade workflow pipelines allows engineering and marketing teams to operationalize complex optimization tasks, transforming static digital assets into continuously optimized publishing engines.
SEO automation is not merely about scheduling blog posts or auto-generating low-quality descriptions. It represents a fundamental architectural discipline that bridges technical SEO, programmatic content infrastructure, data engineering, and artificial intelligence. By connecting REST APIs, headless web crawlers, relational databases, and orchestration platforms like n8n, organizations can build self-healing technical environments that detect site regressions, optimize page performance, generate structured data markup, and publish contextual content at enterprise scale.
This technical guide provides a definitive architectural blueprint for implementing SEO automation tools and building custom automated workflows. We will explore the modern SEO tool stack, detail programmatic keyword and technical audit pipelines, examine AI agent orchestration for search operations, and walk step-by-step through building an end-to-end automated publishing system integrated directly into WordPress.
Architectural Foundations of Modern SEO Automation
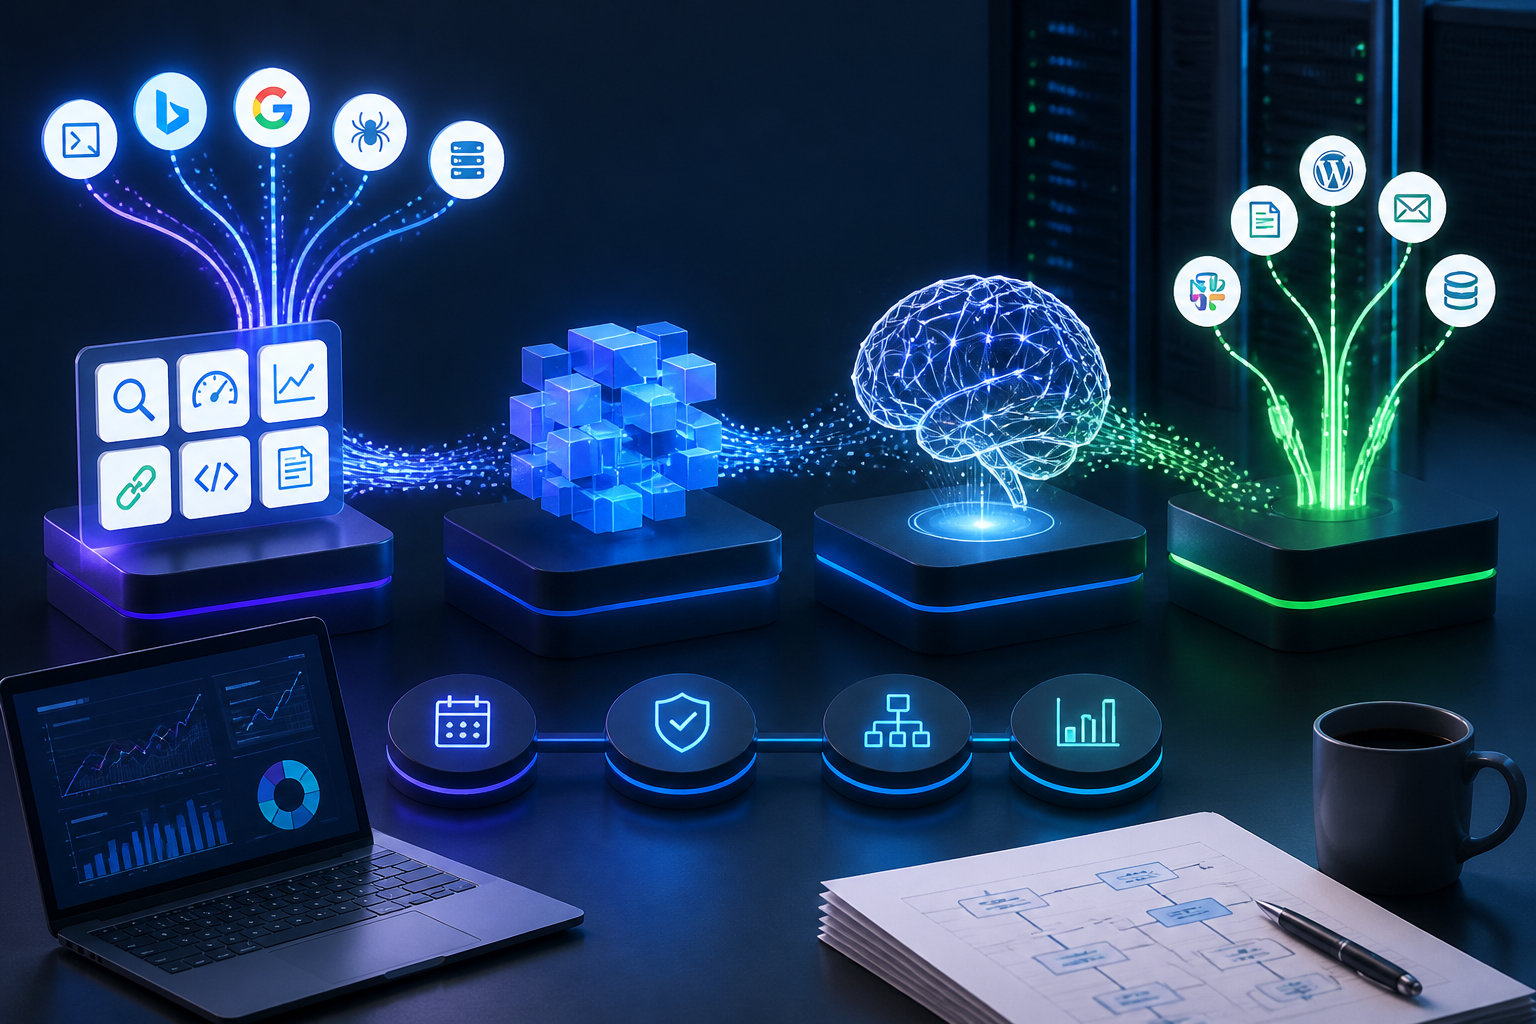
To implement SEO automation successfully, you must view your website and its search performance through the lens of a distributed data system. An enterprise-grade SEO automation architecture consists of four distinct operational layers working in concert: Data Ingestion, Processing & Analysis, Decision Engine, and Action Execution.
Without a structured multi-layer framework, automated SEO scripts often turn into fragile, high-maintenance hacks that break whenever a search engine updates its algorithm or a web platform alters its URL structure. The four-layer model guarantees modularity, security, and technical resilience.
1. Data Ingestion Layer
The ingestion layer continuously gathers raw performance metrics, technical diagnostics, and competitive insights from external and internal endpoints. Rather than relying on human team members to log into analytics platforms, this layer pulls structured data on scheduled intervals or real-time event triggers via webhooks and REST APIs.
- Search Engine APIs: Google Search Console API (indexation, queries, impressions, CTR, position data), Bing Webmaster Tools API, and Google PageSpeed Insights API.
- Third-Party Intelligence APIs: Ahrefs API, Semrush API, DataForSEO, and Moz API for backlink metrics, keyword difficulty scores, and competitor rank tracking.
- Headless Crawling Engines: Screaming Frog CLI, Playwright, Puppeteer, or custom Python Scrapy pipelines for continuous DOM rendering and link extraction.
- Server & Log Sources: Server access logs (Nginx, Apache, Cloudflare Workers), server response code monitors, and CDN edge log streams.
2. Processing & Analysis Layer
Raw JSON responses and log lines must be clean, normalized, and stored before they can drive automated decisions. The processing layer executes data transformation rules, calculates custom performance indicators, converts unstructured HTML text into semantic embeddings, and stores output in relational or vector databases (such as PostgreSQL, Redis, or Qdrant).
For instance, raw Google Search Console performance data is transformed into cannibalization reports by aggregating click distributions across URLs targeting identical keyword clusters. Natural language processing (NLP) models calculate TF-IDF or cosine similarity metrics to measure content completeness against top-ranking search engine results pages (SERPs).
3. Decision & Intelligence Layer
The decision layer determines what action—if any—should be triggered based on processing layer outputs. This layer relies on deterministic business logic combined with heuristic scoring models or LLM-driven decision agents.
For standard technical health, deterministic logic reigns supreme: IF server response code === 404 AND inbound internal links > 5 THEN queue redirect creation task. For content intelligence, probabilistic models evaluate whether an existing article requires an updated section, modified meta markup, or revised internal anchor links. Advanced setups leverage LLMs such as the Google Gemini AI model to analyze structural gaps between top-performing documents and existing published nodes.
4. Action & Execution Layer
The final layer executes changes across your digital footprint. Actions can be entirely autonomous (for safe, non-destructive tasks like updating XML sitemaps or notifying developers of broken links) or semi-autonomous (requiring human approval in a staging interface before updating production systems).
- Headless Content Management: Pushing updates via the WordPress REST API, WooCommerce GraphQL endpoints, or Shopify Admin APIs.
- Notification Engines: Dispatching real-time diagnostic alerts to Slack, Microsoft Teams, or Jira webhooks.
- Edge Worker Execution: Modifying canonical headers, rendering dynamic schema, or setting temporary 301 redirects dynamically at the CDN layer (Cloudflare Workers, Fastly Compute@Edge).
Categorization & Evaluation Matrix of SEO Automation Tools
Selecting the correct software components is essential when constructing an automated SEO stack. The modern software landscape spans several core categories, ranging from traditional desktop crawlers equipped with Command Line Interfaces (CLI) to cloud-native visual workflow engines and specialized programmatic APIs.
The matrix below compares the top categories of seo automation tools, highlighting their primary use cases, automation interface capabilities, and enterprise suitability.
| Tool Category | Representative Platforms | Primary Automation Interface | Key Strengths | Technical Limitations |
|---|---|---|---|---|
| Technical Site Crawlers | Screaming Frog CLI, Sitebulb Server, Lumar (Deepcrawl), ContentKing | CLI Commands, Scheduled Cron Jobs, Real-time Webhooks, REST API | Deep DOM parsing, JS rendering, automated audit diffing, continuous issue reporting. | High resource consumption (memory/bandwidth); requires dedicated server instances for continuous large-scale runs. |
| Data Intelligence APIs | DataForSEO, Ahrefs API, Semrush API, Google Search Console API | JSON REST APIs, GraphQL, gRPC endpoints | Access to massive index databases, real-time rank monitoring, programmatic SERP parsing. | API credit costs scale quickly; rate limits require exponential backoff handling. |
| Workflow Orchestration | n8n, Make, Zapier, Apache Airflow, Prefect | Visual Node Builders, Python DAGs, Webhook Triggers | Integrates disparate APIs, orchestrates conditional logic, manages error handling and retries effortlessly. | Requires strict schema design to prevent infinite loop executions or orphaned workflow state. |
| AI Agent Frameworks | LangChain, LlamaIndex, AutoGen, CrewAI | Python / TypeScript SDKs, REST Microservices | Semantic analysis, intent categorization, automated content optimization, complex decision-making. | Requires strict safety guardrails to prevent AI hallucinations and unverified content output. |
| Programmatic CMS Tools | WordPress REST API, Rank Math API, WP All Import CLI, Headless Strapi | REST APIs, Webhooks, CLI Scripts | Direct programmatic creation and modification of posts, taxonomy tags, meta fields, and redirects. | Requires validation sanitization to prevent database bloating or broken front-end rendering. |
Automated Technical Auditing & Continuous Site Monitoring Engines
Technical SEO degradation occurs silently. A single frontend release can introduce broken canonical tags, misconfigured `noindex` directives, or missing schema fields across thousands of pages. Relying on monthly or quarterly manual technical audits guarantees that search performance penalties will occur long before technical errors are detected.
Automated technical auditing converts periodic testing into continuous quality assurance. By running scheduled headless crawls and integrating site monitoring webhooks directly into deployment pipelines, teams catch structural errors in staging environments or within minutes of reaching production.
Automating Screaming Frog via Command Line Interface (CLI)
Screaming Frog is renowned as a desktop GUI crawler, but its true enterprise utility lies in its Command Line Interface. You can run Screaming Frog headlessly on cloud infrastructure (such as AWS EC2 or a local Ubuntu server), passing configuration files dynamically to execute scheduled crawls, generate exported CSV reports, and dispatch execution payloads to automated pipelines.
Here is an example Bash script designed for continuous Linux execution. It executes a headless crawl against a target domain using pre-configured audit parameters, exports issues to a designated folder, and triggers a downstream processing script:
#!/bin/bash

# Enterprise Technical SEO Crawl Script
# Executes Screaming Frog CLI headlessly and triggers audit webhooks

DOMAINTARGET="https://example.com"
CONFIG_FILE="/etc/screamingfrog/production_audit_config.seospiderconfig"
EXPORT_DIR="/var/log/seo_audits/$(date +%Y-%m-%d)"
WEBHOOK_ENDPOINT="https://n8n.example.com/webhook/technical-seo-alert"

mkdir -p "$EXPORT_DIR"

echo "[+] Starting headless technical SEO crawl for $DOMAINTARGET..."

# Execute Screaming Frog Headless Command
screamingfrogseospider --crawl "$DOMAINTARGET" \
  --headless \
  --config "$CONFIG_FILE" \
  --output-folder "$EXPORT_DIR" \
  --export-tabs "Internal:All,Indexability:Non-Indexable,Response Codes:Client Error (4xx),Response Codes:Server Error (5xx)" \
  --save-crawl

echo "[+] Crawl complete. Processing issue exports..."

# Check for critical 5xx errors in the exported CSV
SERVER_ERRORS=$(wc -l < "$EXPORT_DIR/response_codes_server_error_5xx.csv")

if [ "$SERVER_ERRORS" -gt 1 ]; then
  echo "[!] CRITICAL: Server errors detected ($SERVER_ERRORS pages). Triggering webhook alert..."
  curl -X POST "$WEBHOOK_ENDPOINT" \
    -H "Content-Type: application/json" \
    -d "{
      "event": "critical_crawl_alert",
      "domain": "$DOMAINTARGET",
      "server_errors": $SERVER_ERRORS,
      "report_path": "$EXPORT_DIR"
    }"
fi

echo "[+] Audit pipeline finalized."
Automated Performance Diagnostic Pipelines with Lighthouse CI
Core Web Vitals are directly factored into search rankings and user conversion performance. Instead of manually testing URLs inside PageSpeed Insights, engineers integrate Google’s Lighthouse CI (LHCI) into continuous integration (CI/CD) systems like GitHub Actions or GitLab CI.
Every code deployment automatically spins up headless Chrome instances, measures Largest Contentful Paint (LCP), Cumulative Layout Shift (CLS), and Interaction to Next Paint (INP), and asserts strict performance budgets. If a developer introduces a heavy uncompressed JavaScript bundle that degrades LCP beyond 2.5 seconds, the automated pipeline fails the build before the code reaches production servers.
Programmatic Keyword Research & Entity Graph Automation
Traditional keyword research relies on human operators typing seed terms into SEO platform dashboards, downloading CSV exports, and applying manual pivot tables. Programmatic keyword research automates this cycle by consuming raw search volume, SERP features, and user intent metrics directly through developer APIs, then applying natural language processing (NLP) algorithms to cluster topics at scale.
By shifting from string matching to semantic entity graphs, automated tools organize thousands of keywords into structurally relevant clusters based on SERP overlap rather than literal keyword matches.
Calculating SERP Similarity for Automated Keyword Clustering
Keyword clustering groups search queries that share structural intent. If two different search queries return 6 or more identical URLs in Google’s top 10 search results, those queries share fundamental intent and should be targeted on a single comprehensive page rather than split across two separate articles.
The Python script below illustrates how to programmatically calculate the Jaccard Similarity coefficient between SERP result arrays generated by third-party search APIs (such as DataForSEO or custom Google Custom Search API integrations):
import json
import numpy as np

def jaccard_serp_similarity(serp_list_a, serp_list_b):
    """
    Calculates the Jaccard Similarity Index between two SERP URL arrays.
    Score ranges from 0.0 (completely distinct) to 1.0 (identical SERP).
    """
    set_a = set(serp_list_a)
    set_b = set(serp_list_b)

    intersection = set_a.intersection(set_b)
    union = set_a.union(set_b)

    if not union:
        return 0.0

    return len(intersection) / len(union)

# Example SERP Data retrieved via API for two distinct queries
query_1_urls = [
    "https://example.com/best-seo-tools",
    "https://techdomain.org/top-seo-software",
    "https://industrynews.net/seo-automation-guide",
    "https://rankchecker.io/tools-list",
    "https://searchenginesite.com/software-review"
]

query_2_urls = [
    "https://example.com/best-seo-tools",
    "https://techdomain.org/top-seo-software",
    "https://industrynews.net/seo-automation-guide",
    "https://bloghub.com/marketing-tech-stack",
    "https://softwarecomparisons.com/seo-platforms"
]

similarity_score = jaccard_serp_similarity(query_1_urls, query_2_urls)
print(f"SERP Similarity Score: {similarity_score:.2f}")

if similarity_score >= 0.40:
    print("[*] Decision: Cluster queries into a single master topic page.")
else:
    print("[*] Decision: Target queries on distinct dedicated landing pages.")
Integrating this logic into automated content planning engines ensures that your site never creates internal keyword cannibalization issues. The automated system tags incoming search terms, groups them into logical entity nodes, and outputs content specifications directly to editorial teams or automated drafting platforms.
AI-Driven Content Generation & On-Page Optimization Pipelines
The intersection of generative AI and search engine optimization has given rise to sophisticated content operations pipelines. However, reckless deployment of raw text-generation scripts produces thin, repetitive content that fails Google’s Helpful Content System metrics and damages domain trust.
High-performing automated content operations utilize multi-agent orchestration frameworks. Instead of firing off a single prompt (e.g., “Write an article about SEO tools”), the content generation workflow is divided into specialized, deterministic stages, each governed by specific validation rules, schema requirements, and quality checks.
Multi-Agent Content Orchestration Architecture
- Serp & Gap Analysis Agent: Scrapes current top 10 search results for target queries, extracts main headings (H2/H3), identifies structural patterns, and determines semantic entities missing from top results.
- Outline Engineering Agent: Generates a strict structural outline formatted in JSON, defining explicit section goals, target entity insertions, direct-answer summary requirements, and code/table inclusions.
- Drafting & Technical Agent: Receives structural specifications and executes deep context writing. Utilizes advanced coding platforms or specialized developer systems such as the Google Antigravity environment to compile, test, and render complex code examples and technical setups directly into content drafts.
- Safety & Optimization Audit Agent: Evaluates generated content against strictly defined enterprise guardrails: scans for structural repetition, checks fact accuracy, verifies anchor link formatting, ensures strict adherence to target search intent, and enforces tone consistency.
By enforcing modular multi-step processing, digital organizations maintain absolute quality control while enjoying the velocity benefits of automated generation engines. Implementing dedicated WordPress content automation pipelines allows enterprise publishing systems to automatically ingest these verified drafts, format custom post types, populate ACF (Advanced Custom Fields) metadata, and stage items for editor review.
Building an End-to-End Automated SEO Pipeline with n8n and WordPress
To demonstrate practical SEO automation, we will walk through constructing an enterprise-grade automated content creation and SEO publishing pipeline using n8n (a powerful, self-hosted node-based workflow orchestration platform) and the standard WordPress REST API.
This pipeline handles the full lifecycle of automated page optimization: receiving target research metrics via Webhook, generating semantic content specifications, creating automated JSON-LD schema, publishing the draft to WordPress, and dispatching an instant indexation ping to search engines.
Pipeline Workflow Visual Architecture
[ Webhook Trigger: New Keyword Payload ]
                   │
                   ▼
[ Node 1: Fetch Existing Category Context (WP REST API) ]
                   │
                   ▼
[ Node 2: Generate Content & Meta via LLM API ]
                   │
                   ▼
[ Node 3: Validate HTML & Format Schema Payload ]
                   │
                   ▼
[ Node 4: Create WordPress Post Draft (WP REST API) ]
                   │
                   ▼
[ Node 5: Dispatch Alert to Slack & Log Run ]
Detailed Step-by-Step Implementation Guide
Step 1: Configuring the Incoming Webhook Node in n8n
In n8n, create a new workflow and add a Webhook Trigger. Set the HTTP Method to POST and define the path as seo-content-pipeline. This node receives automated keyword data from your research database or external API engines.
The incoming JSON payload structure must adhere to the following schema:
{
  "target_keyword": "seo automation tools",
  "category_id": 12,
  "target_slug": "seo-automation-tools-guide",
  "content_intent": "Informational",
  "secondary_keywords": [
    "automated technical seo",
    "n8n seo automation",
    "seo reporting tools"
  ]
}
Step 2: Processing Content Generation via OpenAI / Gemini Node
Connect an HTTP Request node or the native LLM Chain node to pass the payload parameters into a structured prompt. The system prompt must enforce output formatting rules, mandating clean HTML markup (no wrap tags like <html> or <body>), explicit heading levels (starting strictly with <h2>), and direct-answer structure.
For complex publishing workflows involving granular post creation logic, review our operational guide on setting up n8n WordPress post creation workflows.
Step 3: Interacting with the WordPress REST API
To communicate securely with WordPress, create an Application Password in your WordPress Admin dashboard (Users -> Profile -> Application Passwords). Add an HTTP Request node inside n8n with basic HTTP Authentication using your admin username and generated application password.
Configure the HTTP node as follows:
- Method: POST
- URL:
https://yourdomain.com/wp-json/wp/v2/posts - Headers:
Content-Type: application/json
Map the n8n data payload into the WordPress API HTTP body using the following raw JSON body structure:
{
  "title": "SEO Automation Tools: Complete Technical & Operational Blueprint",
  "slug": "={{ $json.body.target_slug }}",
  "status": "draft",
  "content": "={{ $json.generated_html }}",
  "excerpt": "={{ $json.generated_excerpt }}",
  "categories": ["={{ $json.body.category_id }}"],
  "meta": {
    "_yoast_wpseo_focuskw": "={{ $json.body.target_keyword }}",
    "_yoast_wpseo_metadesc": "={{ $json.generated_meta_description }}"
  }
}
When Rank Math or Yoast SEO is installed, their custom meta keys can be populated directly via the standard WordPress post payload, provided custom meta fields are exposed to the REST API in your theme’s functions.php file.
Automated Schema Markup & Structured Data Generation
Structured data (JSON-LD) translates human-readable content into explicit, machine-understandable entity relationships for search crawlers. Manually scripting JSON-LD blocks for hundreds of deep technical articles or e-commerce products is time-consuming and prone to syntax errors like unescaped double quotes or missing bracket pairs.
Automated SEO tools build schema payloads dynamically during the publishing process, extracting page attributes directly from post objects and generating clean, error-free JSON-LD snippets embedded directly into the target page head.
Programmatic Schema Generation Script
Below is a Node.js helper utility designed to construct an enterprise-grade `TechArticle` and `FAQPage` JSON-LD schema payload dynamically. This script can be executed inside an n8n Code Node or deployed as a microservice endpoint:
/**
 * Dynamic JSON-LD Schema Generator for Technical SEO Pipelines
 */
function generateTechnicalArticleSchema(articleData, faqList) {
  const baseDomain = "https://advancedworkflows.shop";

  // Construct Primary TechArticle Schema
  const articleSchema = {
    "@context": "https://schema.org",
    "@type": "TechArticle",
    "mainEntityOfPage": {
      "@type": "WebPage",
      "@id": `${baseDomain}/${articleData.slug}/`
    },
    "headline": articleData.title,
    "description": articleData.metaDescription,
    "inLanguage": "en-US",
    "author": {
      "@type": "Organization",
      "name": "Advanced Workflows SEO Engineering",
      "url": baseDomain
    },
    "publisher": {
      "@type": "Organization",
      "name": "Advanced Workflows",
      "logo": {
        "@type": "ImageObject",
        "url": `${baseDomain}/assets/logo.png`
      }
    },
    "datePublished": articleData.publishDate,
    "dateModified": articleData.modifiedDate || articleData.publishDate,
    "dependencies": articleData.technicalDependencies || "n8n, WordPress REST API, Node.js"
  };

  // Construct FAQ Schema if array exists
  let faqSchema = null;
  if (Array.isArray(faqList) && faqList.length > 0) {
    faqSchema = {
      "@context": "https://schema.org",
      "@type": "FAQPage",
      "mainEntity": faqList.map(item => ({
        "@type": "Question",
        "name": item.question,
        "acceptedAnswer": {
          "@type": "Answer",
          "text": item.answer
        }
      }))
    };
  }

  return {
    articleSchemaJson: JSON.stringify(articleSchema, null, 2),
    faqSchemaJson: faqSchema ? JSON.stringify(faqSchema, null, 2) : null
  };
}

// Example Usage
const mockArticle = {
  title: "SEO Automation Tools: Enterprise Blueprint",
  slug: "seo-automation-tools-guide",
  metaDescription: "Complete guide to modern SEO automation software.",
  publishDate: "2026-03-30T08:00:00Z"
};

const mockFaqs = [
  {
    question: "What are SEO automation tools?",
    answer: "SEO automation tools are software solutions that programmatic optimize site workflows."
  }
];

const generatedSchema = generateTechnicalArticleSchema(mockArticle, mockFaqs);
console.log(generatedSchema.articleSchemaJson);
Injecting this dynamic JSON-LD block automatically into header templates via WordPress hooks guarantees perfect structured data compliance without requiring post-by-post manual coding.
Internal Linking Automation & Graph Analysis
Internal links distribute PageRank, establish topical context hierarchies, and help search engines discover newly published nodes. However, manual internal link insertion scales poorly. As site archives expand into thousands of articles, legacy content rarely links back to newly created posts, starving new URLs of internal link authority.
Automated internal linking tools solve this by treating your website content database as a multi-directional graph network. By deploying mathematical graph algorithms and vector embedding search, automated link engines systematically connect related nodes across your whole architecture.
How Automated Semantic Graph Linking Functions
- Document Embedding: When a new page is generated, its core context is converted into a multi-dimensional vector embedding via vector generation models (such as OpenAI
text-embedding-3-smallor open-source HuggingFace models). - Vector Database Search: The system queries a vector database (e.g., Qdrant, Pinecone) containing vector representations of all existing site pages to identify the top 5-10 most semantically similar existing documents.
- Anchor Entity Extraction: The automated script inspects those historical documents for candidate sentences matching exact or partial variations of the new document’s target entity.
- REST API Injection: The system programmatically edits the target historical HTML documents via the CMS REST API, seamlessly inserting contextual anchor links pointed at the new URL.
Integrating modern agentic workflow architecture enables these internal link generation steps to run autonomously in the background whenever a fresh piece of content moves from staging to production.
Log File Analysis & Automated Search Engine Crawler Tracking
Analytics tools like Google Analytics only record user client activity; they tell you nothing about how search engine crawlers interact with your underlying web infrastructure. Server log file analysis reveals the raw, unfiltered reality of search engine behavior: crawl frequency, status code distributions, crawl budget allocation, and orphan page rendering attempts.
Automating log analysis transforms passive web server logs into dynamic technical diagnostic dashboards, allowing you to catch indexing bottlenecks before they impact rankings.
Building an Automated Nginx Crawl Monitor
By parsing Nginx or Apache access logs in real time, automated scripts isolate requests made by verified user agents (such as Googlebot or Bingbot) and evaluate HTTP status codes. If Googlebot hits a high volume of 5xx server errors or 301 redirect chains within a short window, an instant alert is triggered.
The Python script below illustrates how to parse an Nginx log stream, filter for crawler activity, and report status distributions programmatically:
import re
from collections import Counter

# Nginx Combined Log Pattern Regex
LOG_PATTERN = re.compile(
    r'(?P<ip>[\d\.]+) - - \[(?P<date>[^\]]+)\] "(?P<method>GET|POST) (?P<url>\S+) HTTP/\d\.\d" (?P<status>\d{3}) (?P<bytes>\d+) "[^"]*" "(?P<user_agent>[^"]*)"'
)

KNOWN_CRAWLERS = ["Googlebot", "bingbot", "DuckDuckBot", "YandexBot"]

def process_server_logs(log_file_path):
    crawler_status_counts = Counter()
    crawled_urls = []

    with open(log_file_path, 'r') as log_file:
        for line in log_file:
            match = LOG_PATTERN.match(line)
            if match:
                data = match.groupdict()
                ua = data['user_agent']

                # Identify search engine crawler
                if any(bot in ua for bot in KNOWN_CRAWLERS):
                    status = data['status']
                    url = data['url']
                    crawler_status_counts[status] += 1
                    crawled_urls.append(url)

    print("--- Search Engine Crawler Status Code Summary ---")
    for status_code, count in crawler_status_counts.items():
        print(f"HTTP Status {status_code}: {count} requests")

    return crawler_status_counts

# Execute Log Processing
# process_server_logs("/var/log/nginx/access.log")
Automating this processing on a night cron schedule guarantees that technical teams maintain complete transparency over search engine crawl distribution and infrastructure efficiency.
Addressing Common Edge Cases, System Failures, & Safety Guardrails
Automating SEO tasks brings efficiency, but unmonitored automation introduces significant operational risk. A misconfigured script can overwrite meta descriptions across thousands of production pages, introduce recursive redirect loops, or flood your CMS with unverified content. Designing robust, self-healing automation systems requires setting strict engineering guardrails.
1. Rate Limits & Exponential Backoff Handling
Third-party APIs (Ahrefs, Semrush, Google Search Console) impose strict rate caps. Automated workflows must implement exponential backoff retry mechanisms. When an API endpoint responds with an HTTP 429 (Too Many Requests), the automation platform should pause execution, wait exponentially increasing intervals (e.g., 2s, 4s, 8s, 16s), and retry the request automatically rather than crashing the workflow execution state.
2. Infinite Loop Prevention in CMS Webhooks
A common vulnerability in automated CMS workflows occurs when a post update webhook triggers an automated optimization script, which in turn saves the post, firing another post update webhook. This creates an infinite execution loop that rapidly consumes server resources and exhausts API credits. Always check webhook payload event flags or add custom metadata parameters (e.g., _automated_update_processed = true) to short-circuit recursive execution loops.
3. Content Hallucination & Fact-Checking Filters
Generative AI engines can output unverified claims, incorrect dates, or non-existent API parameters. Automated content generation pipelines must pass generated text through deterministic validation regex steps and entity extractors before publishing. Critical technical details, numerical statistics, and code syntax snippets should be verified using automated sandbox execution environments prior to rendering production HTML.
Troubleshooting & Maintenance Operations for Automated SEO Systems
Even well-architected SEO automation tools encounter technical degradation over time. Upstream API endpoints update their response schemas, web platforms change CSS selectors, and database sizes expand. Regular troubleshooting and operational maintenance are required to keep automated search engines running smoothly.
Use the following operational diagnostic table to identify and resolve common structural failure modes across automated SEO systems:
| Symptom / Operational Failure | Probable Root Cause | Diagnostic Step | Remediation Strategy |
|---|---|---|---|
| Automated WordPress REST API Requests Fail (HTTP 401/403) | Expired Application Password, missing user capabilities, or security plugin blocking REST endpoints. | Inspect HTTP headers returned by WordPress; verify user role permissions in WP Admin. | Regenerate Application Passwords; whitelist automation server IP in Wordfence/iThemes Security rules. |
| n8n Workflow Halts on Node Execution | Payload structural mismatch, unescaped JSON strings, or third-party API timeout. | Open n8n Execution History log; check raw JSON input/output schema for structural drift. | Add `Continue on Fail` branch logic; wrap JSON outputs in strict string sanitization nodes. |
| Crawlers Exceed Server Memory Allocation | Headless Chrome or Screaming Frog CLI exceeding system RAM limits during large crawls. | Monitor server memory usage (`htop` or CloudWatch metrics) during cron crawl runs. | Restrict crawl depth limits; allocate swap space; convert desktop CLI jobs to cloud-distributed microservices. |
| Duplicate Page Creation in CMS | Missing unique slug validation prior to REST API post insertion. | Query WordPress database via REST API for existing post slug match before executing POST payload. | Implement deterministic check-before-create logic: `GET /wp/v2/posts?slug={target_slug}`. |
Addressing Common Questions (PAA & Industry Inquiries)
As enterprise teams transition to automated SEO models, critical questions emerge regarding safety, monetization, job stability, and AI platform integration. Below are technical breakdowns answering the most prominent industry inquiries.
How to Automate AI Content Safely?
Automating AI content safely requires separating generation logic from publication workflows. You should never deploy raw output straight from an LLM directly to live web pages. Instead, construct a multi-stage validation engine. First, apply programmatic rules to filter out generic phrasing and ensure target heading structures. Second, validate semantic keyword coverage against top SERP benchmarks. Third, inject verified schema markup and contextual internal links programmatically. Finally, push the assembled HTML into a drafting queue where human editors verify technical precision and brand alignment prior to live publication.
How Can Organizations Leverage AI Workflows to Drive Significant Digital Value?
Generating substantial revenue or organizational efficiency using AI requires shifting focus from manual one-off text prompts to building high-velocity asset generation platforms. Organizations achieve maximum ROI by deploying programmatic SEO architectures: capturing long-tail search intent at scale across thousands of structured dynamic landing pages (e.g., location directories, integration libraries, template databases). By automating data gathering, page creation, schema rendering, and continuous performance optimization, digital enterprises reduce cost per acquisition while rapidly expanding total organic keyword footprint.
Which Jobs Will Thrive in the Era of SEO Automation?
As basic tasks like manual keyword collection, simple copy drafting, and basic meta tag creation become fully automated, strategic and engineering roles become exponentially more valuable. Technical SEO Engineers who build custom API connectors and manage data infrastructure will thrive. Similarly, Semantic Content Architects, Systems Operations Specialists, and Data Analysts who interpret search log streams and build agentic guardrails will lead organic search strategy. Strategic oversight, creative brand positioning, and complex system engineering remain uniquely human capabilities.
Frequently Asked Questions
What are SEO automation tools?
SEO automation tools are software solutions, APIs, and workflow platforms designed to execute repetitive search engine optimization tasks without manual human intervention. These tools automate activities such as technical site crawling, rank tracking, keyword clustering, internal link generation, schema markup injection, log file analysis, and real-time performance alerting.
Can you fully automate technical SEO?
Many technical SEO tasks can be fully or semi-automated, including XML sitemap generation, structured data injection, continuous 404 error tracking, performance auditing via Lighthouse CI, and canonical tag validation. However, diagnosing complex architectural issues, planning structural site migrations, and overseeing core site migrations still require human engineering expertise.
Is automated content indexed and ranked by Google?
Google ranks content based on quality, relevance, and user value, regardless of how it is produced. Content created using automation and AI tools can rank highly provided it satisfies search intent, demonstrates factual precision, avoids spam policy violations, and delivers genuine information value to users.
How does n8n compare to Zapier for SEO automation?
n8n is an open-source, highly flexible workflow automation engine that can be self-hosted on your own infrastructure, providing unlimited execution runs, privacy control, and low operating costs for high-volume data operations. Zapier offers a managed cloud service with simpler setup but becomes prohibitively expensive when handling large enterprise datasets or high-frequency API calls.
What is the difference between automated SEO and programmatic SEO?
Automated SEO refers to using scripts, workflows, and software to perform routine SEO tasks (such as auditing, reporting, and link checking). Programmatic SEO is a specific publishing architecture that uses code, databases, and structural templates to dynamically build thousands of search-optimized web pages designed to capture long-tail query patterns.
Conclusion & Technical Execution Roadmap
Deploying seo automation tools and constructing custom programmatic pipelines transforms organic search operations from a slow, manual effort into an agile, engineering-driven technical strategy. By building multi-layer architectures—connecting continuous ingestion, automated analysis, decision logic, and automated CMS updates—organizations scale their digital footprint, maintain pristine technical health, and react instantly to search engine updates.
To implement SEO automation within your digital infrastructure, follow this prioritized technical roadmap:
- Establish Headless Diagnostics: Set up automated Screaming Frog CLI or Lighthouse CI scripts to monitor technical health and performance budgets on cron schedules.
- Deploy an Orchestration Platform: Provision a self-hosted instance of n8n to connect your primary tools, database platforms, and WordPress REST API endpoints.
- Automate Structural Markup: Implement server-side or microservice-driven dynamic JSON-LD schema generation for all publishing post types.
- Build Semantic Link Graphs: Integrate vector embeddings to automate internal anchor link creation across legacy content archives.
- Enforce Quality Guardrails: Implement strict content verification logic, validation schemas, and rate-limit handling across all automated execution steps.
By treating search optimization as an engineered software system rather than a series of manual checklists, modern organizations secure a permanent competitive advantage in modern search engine visibility.
